01 · Client overview
Client overview
About Sirovate
Sirovate is a key player in the Life Sciences industry, focusing on enhancing clinical trials with its AI-based platform and workflow suite. Specializing in regulatory medical writing, transparency, and publications, Sirovate provides robust data privacy solutions that improve drug development and patient care.
02 · Challenge
Challenge
Compiling a Plain Language Summary (PLS) traditionally involves synthesizing a vast array of documents and datasets, from trial protocols and results to patient data and lab reports. This process is typically manual, time-consuming, and error-prone, requiring meticulous attention to detail to ensure that all relevant data is accurately included in the appropriate sections of the report.
Existing AI solutions for automating the generation of PLS often struggle to handle the diversity of clinical data effectively. This complexity demands highly precise AI applications, as traditional information retrieval methods struggle with the detailed nuances necessary for accuracy.
03 · Solution
Solution
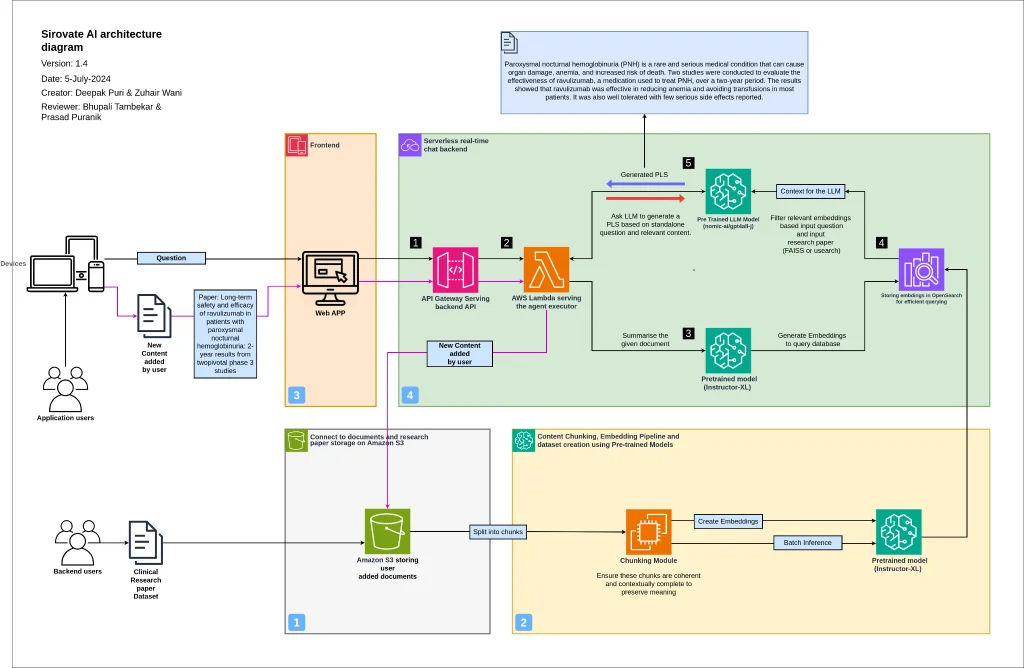
In this solution for clinical research, a secure, scalable, and compliant architecture is employed to handle large datasets, embedding generation, and search capabilities for highly regulated industries like healthcare and pharmaceuticals.
1. Dataset Storage (Amazon S3)
-
Centralized Repository: All clinical research papers and datasets are securely stored in Amazon S3. Each customer has a separate S3 bucket to meet industry compliance regulations (e.g., HIPAA, GDPR). These buckets serve as the primary repository for the unstructured data, including research papers, which need to be ingested and processed.
-
Data Security: Each S3 bucket is encrypted using AWS Key Management Service (KMS), and every customer has a unique encryption key (CMK). This ensures strong data isolation, keeping sensitive clinical data safe and meeting stringent regulatory requirements.
2. Embedding Generation and Storage (Amazon SageMaker and OpenSearch)
-
Embedding Creation: Using the Instructor-XL model hosted in Amazon SageMaker, the content from the clinical research papers in S3 is ingested and split into coherent chunks. The model creates embeddings for each chunk.
-
Vector Database (Amazon OpenSearch): Once embeddings are created, they are stored in a vector database within Amazon OpenSearch. Since the customers are from regulated industries, data from each customer is stored in separate OpenSearch clusters, ensuring data segmentation and meeting compliance needs. This separation ensures there are no data overlaps, and each customer’s embeddings are kept secure in isolated environments.
-
Encryption: All data stored in the vector database (OpenSearch clusters) is encrypted using unique customer-managed keys (CMKs) in AWS KMS, ensuring data security and maintaining privacy for each customer’s sensitive clinical research data.
Generation of PLS:
-
User Input and Chunking: When a user submits their clinical research paper through the frontend web application, it is first split into smaller chunks using the same Instructor-XL model in Amazon SageMaker. These chunks are then converted into embeddings, which are used to perform a search on the pre-stored relevant embeddings in Amazon OpenSearch.
-
Relevant Embedding Search: The system identifies the most relevant research content based on the user input by querying the OpenSearch database for similar embeddings. This helps in providing context-aware results from the research papers.
-
PLS Generation: Using the context provided by the user's input and the relevant embeddings, the final PLS is generated. The nomic-ai/gpt4all-j model hosted in Amazon SageMaker is used to generate this summary, leveraging the matched embeddings to create an accurate and context-rich summary of the research paper.
Key Features of the Architecture
-
Easier iterations and deployment of models using Amazon Sagemaker: Amazon SageMaker plays a critical role in both embedding generation and inference. It enables the use of advanced machine learning models like Instructor-XL and nomic-ai/gpt4all-j for content ingestion, embedding generation, and PLS creation. SageMaker's managed infrastructure reduces the operational complexity of running large-scale ML workloads while ensuring high availability and seamless integration with other AWS services. This makes it easier to iterate, improve, and deploy models quickly and securely.
-
Data Security and Compliance: Every customer's data is stored in isolated S3 buckets and separate OpenSearch clusters, each encrypted with unique CMKs to meet strict data security and regulatory standards.
-
Scalability: Using Amazon S3 for data storage and SageMaker for model inference allows the architecture to scale based on the size of datasets and the number of customers.
-
Efficient Data Retrieval: Embedding-based search via OpenSearch provides efficient and quick access to relevant research, ensuring fast generation of personalized summaries.
-
Custom PaaS Boundaries: By maintaining separate clusters for each customer, the architecture ensures multi-tenant environments are securely isolated, offering a fully compliant platform-as-a-service (PaaS) solution.
04 · Results
Results
-
Faster PLS Generation: Reduced the time to produce Plain Language Summaries from months to weeks.
-
Improved Accuracy: Reduced compliance-related errors by 50%, ensuring higher data integrity and reliability.
-
Enhanced Regulatory Compliance: Exceeded expectations in accuracy and compliance, simplifying the approval process.
-
Scalability: Amazon SageMaker provided a scalable solution to manage growing datasets without compromising performance.
-
Data Security and Privacy: Isolated data storage and encryption using AWS services ensured compliance with industry regulations and maintained strong data privacy boundaries.